Extract Crawl Mode API
Crawl mode follows links on the same website, level by level, and returns every page it visits in
pages, with the same fields as a scrape result plus its url and
depth. It stops at max_pages or max_depth.
API parameters
Mode
mode
Optional
Parameter defines the extraction mode. It can be set to:scrape (default) - Extract a single page.map - List the website's URLs from the page links and sitemaps.crawl - Follow links on the same website and extract every page visited.
Crawl mode consumes one search credit per successfully extracted page.
Crawl & map settings
max_pages
Optional
Used with mode=crawl. Parameter defines the maximum number of pages to extract, including the starting page. Default: 10. Maximum: 100. Each successfully extracted page consumes one search credit.
Crawl Credit Usage
Crawl mode consumes one search credit per successfully extracted page, including the starting page, so max_pages=10 can cost up to 10 credits. Failed pages and cached responses are not charged. search_metadata.credits_consumed shows the cost.
API examples
Crawl an origin mode: crawl
{
  ...
  "search_metadata": {
    "credits_consumed": 3
  },
  "pages": [
    {
      "url": "https://books.toscrape.com/",
      "depth": 0,
      "serpapi_extract_link": "https://serpapi.com/search.json?device=desktop&engine=extract&max_depth=1&max_pages=3&url=https%3A%2F%2Fbooks.toscrape.com%2F",
      "page_information": { "title": "All products | Books to Scrape - Sandbox" },
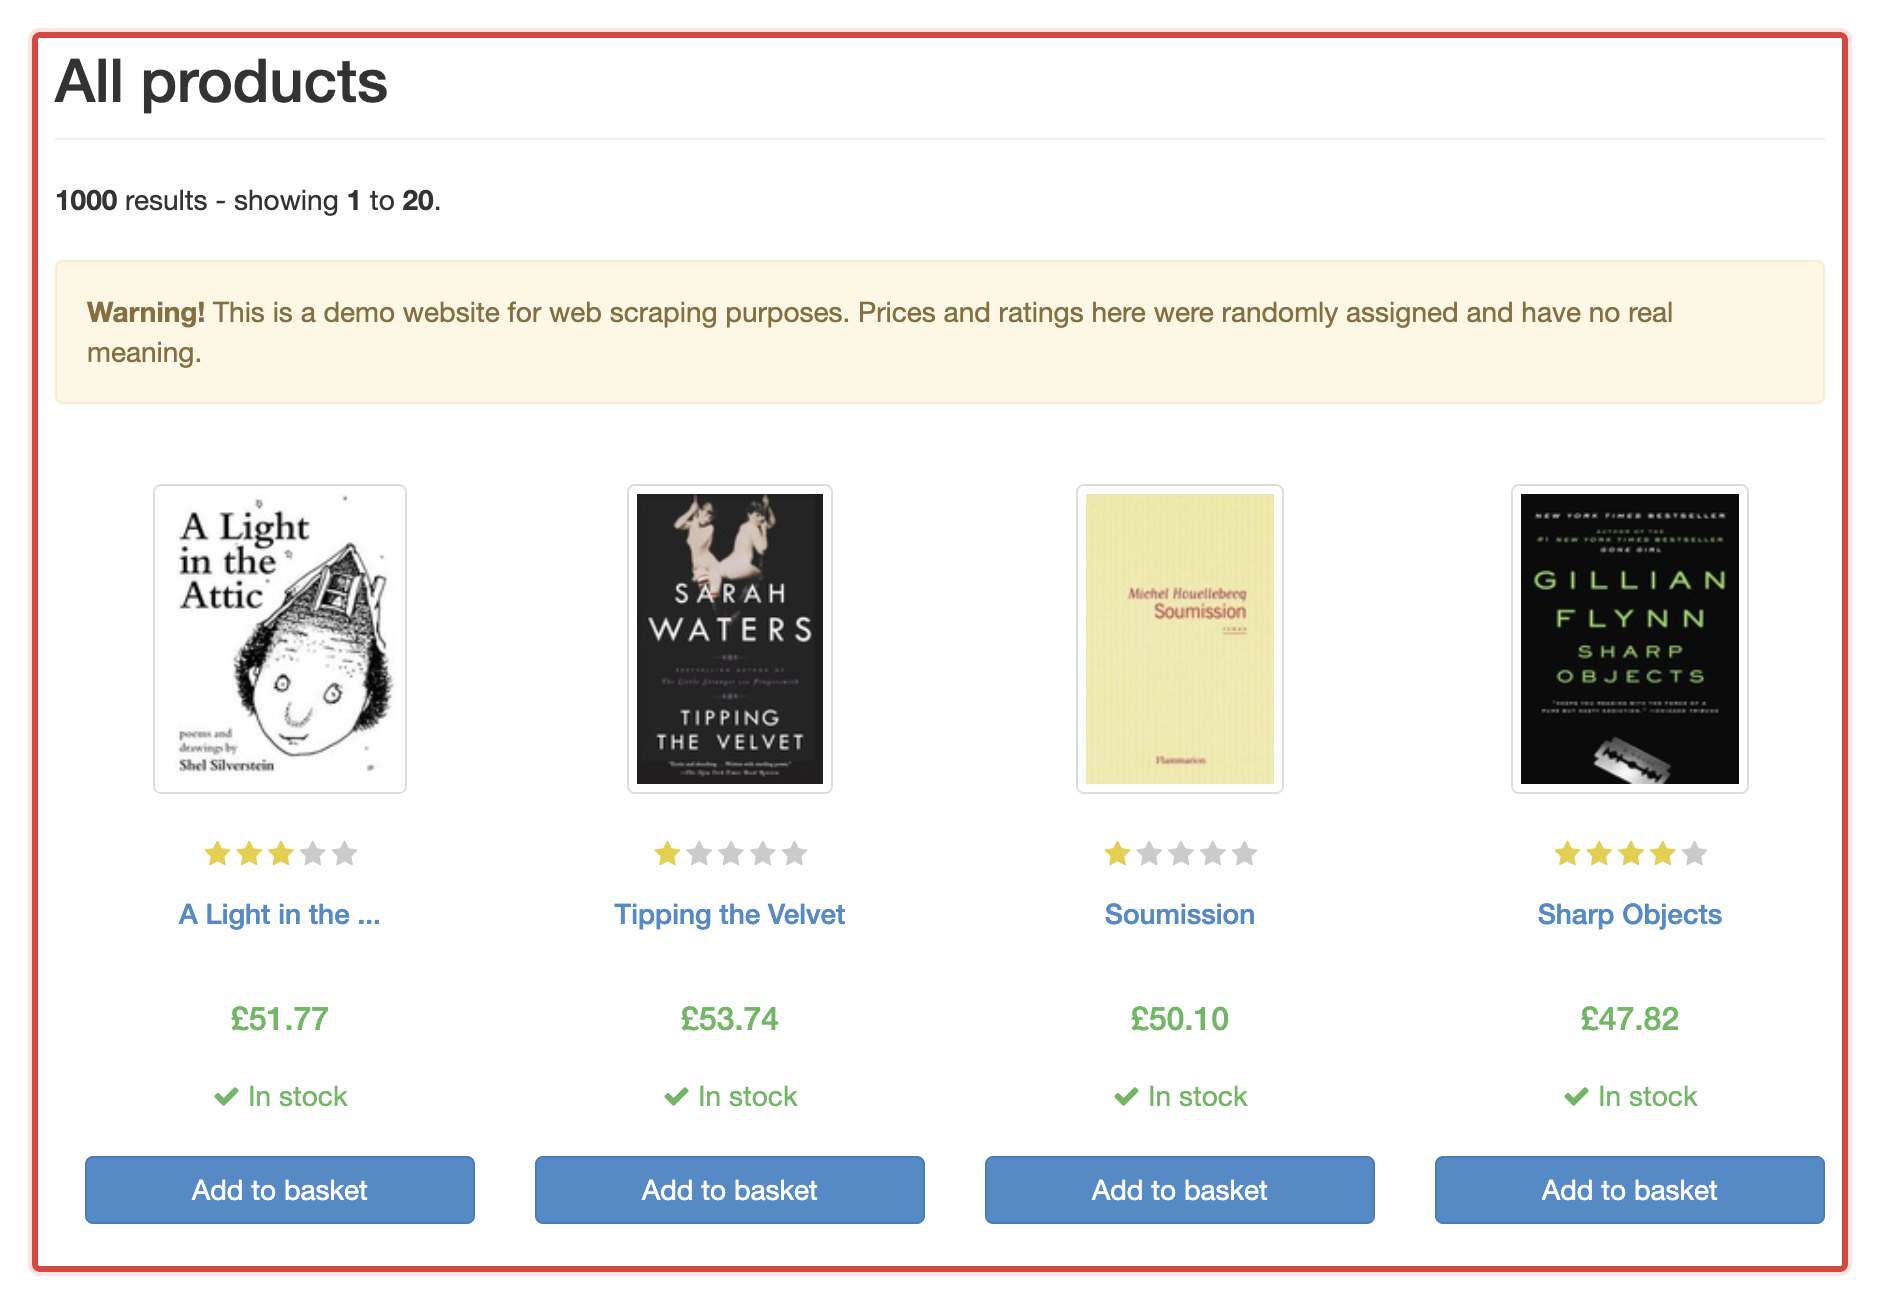
      "markdown": "[Books to Scrape](https://books.toscrape.com/index.html) We love being scraped!\n\n- [Home](https://books.toscrape.com/index.html)\n- All products\n\n..."
    },
    {
      "url": "https://books.toscrape.com/index.html",
      "depth": 1,
      "serpapi_extract_link": "https://serpapi.com/search.json?device=desktop&engine=extract&max_depth=1&max_pages=3&url=https%3A%2F%2Fbooks.toscrape.com%2Findex.html",
      "page_information": { "title": "All products | Books to Scrape - Sandbox" }
    },
    {
      "url": "https://books.toscrape.com/catalogue/category/books_1/index.html",
      "depth": 1,
      "serpapi_extract_link": "https://serpapi.com/search.json?device=desktop&engine=extract&max_depth=1&max_pages=3&url=https%3A%2F%2Fbooks.toscrape.com%2Fcatalogue%2Fcategory%2Fbooks_1%2Findex.html",
      "page_information": { "title": "Books | Books to Scrape - Sandbox" }
    }
  ]
}
JSON structure overview
{
  ...
  "pages": [
    {
      "url": "String - URL of the page",
      "depth": "Integer - Number of links followed from the starting page, 0 for the starting page",
      "serpapi_extract_link": "String - Extract API link for extracting this URL next",
      "error": "String - Error message, if the page couldn't be extracted",
      "page_information, markdown, inline_links, ...": "Same sections as a scrape result"
    },
    ...
  ]
}